Work Text:
Chapter 3: How it works
Chapter Text
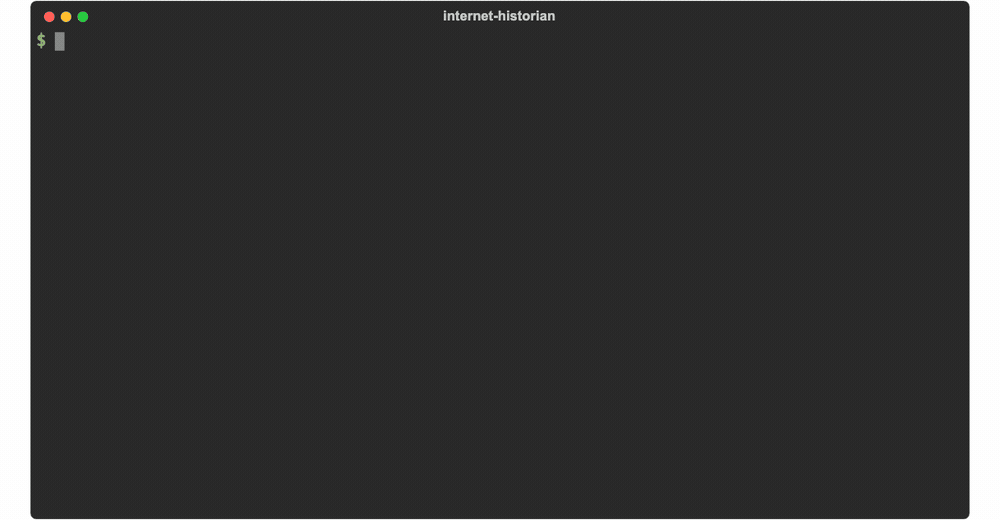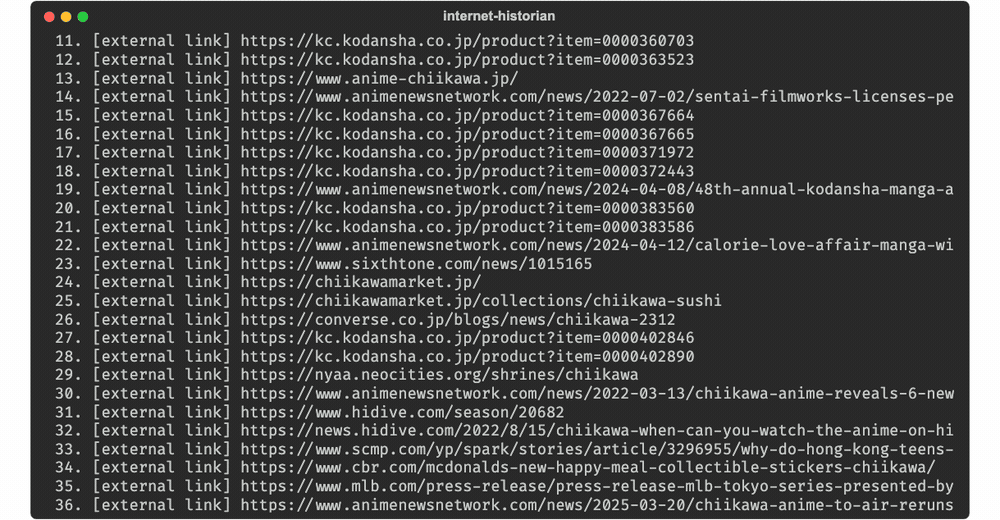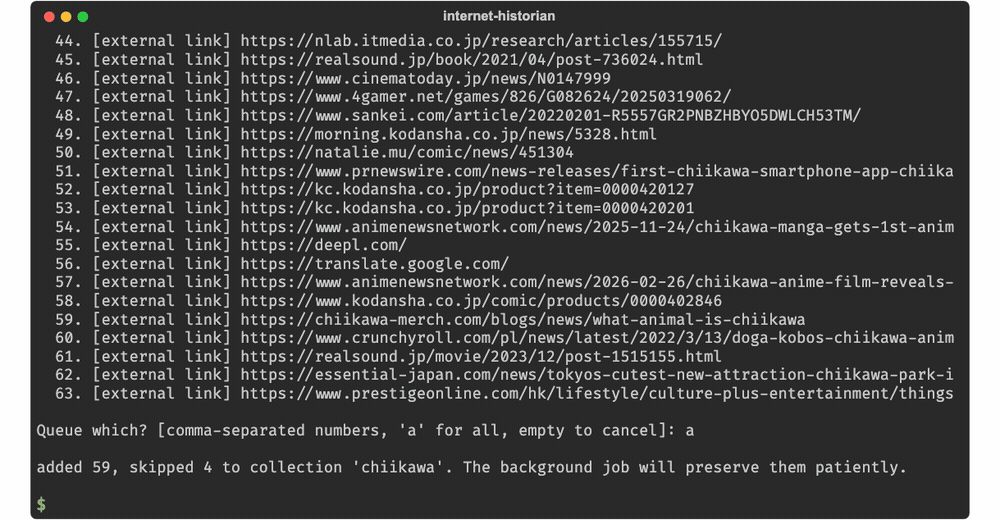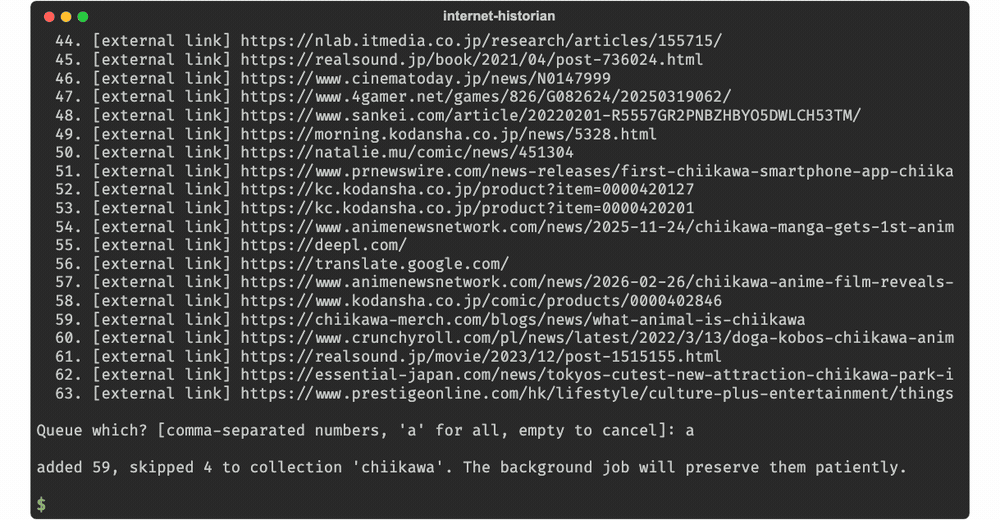
You feed it pages three ways: paste URLs, import a browser bookmarks export, or use discover, which takes a subject ("Chiikawa") and finds its official site, Wikipedia article, and real external links with zero API keys. The demo recording in the README is a real run: discover found and queued 63 genuine Chiikawa pages.
Everything lands in a local SQLite queue that a background job drains every ten minutes. Pages move from queued to submitted to archived, and a page is only marked dead after three failed confirmations spaced a day apart, because a throttled Archive is not a dead URL. If the Archive is busy, the queue waits and tries again until the capture is confirmed.